
AI Regression Testing: Versioned Evidence for Financial AI Systems
A practical method for AI regression testing: freeze the system and tests, inspect individual transitions, and preserve failures beside improvements.
Read the paperNikxius Research / 26 September 2026
Evaluate the system. Inspect the change. Bound the action.
Research on AI evaluation, financial governance and agentic safety—built around explicit methods, source notes and the limits of what a result can establish.
Current papers
Research synthesis + engineering analysisA practical method for AI regression testing: freeze the system and tests, inspect individual transitions, and preserve failures beside improvements.
Read the paperHow financial AI governance connects intended use, evaluation results, provenance and human review—and where the evidence stops.
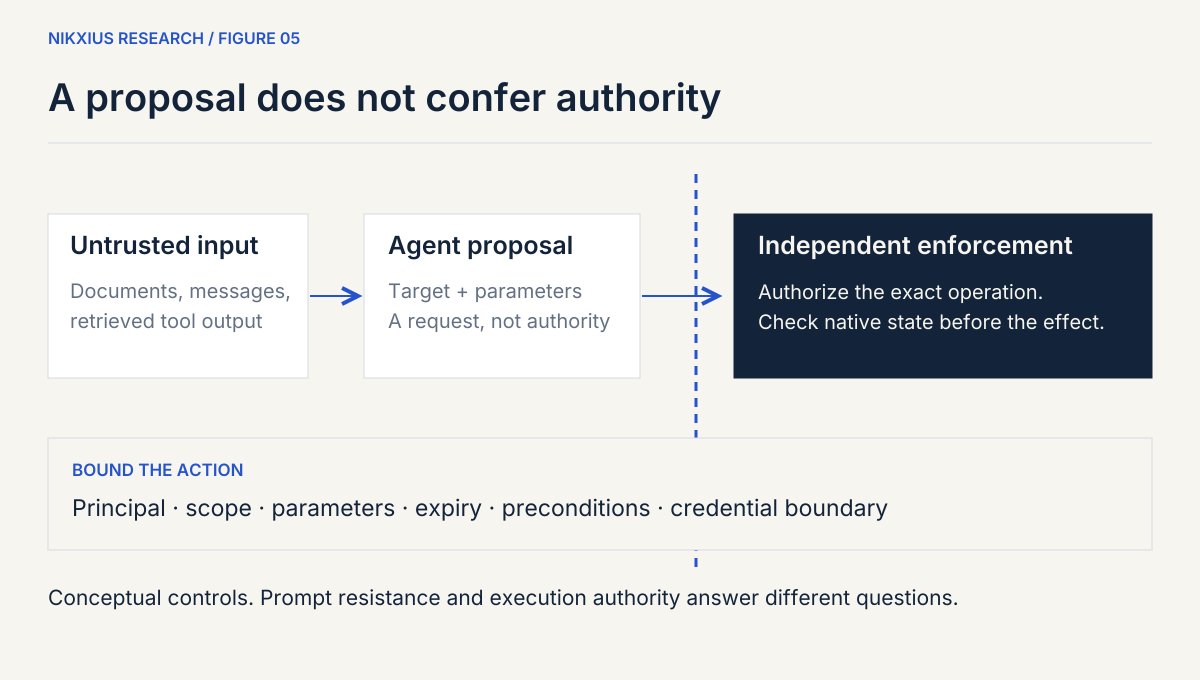
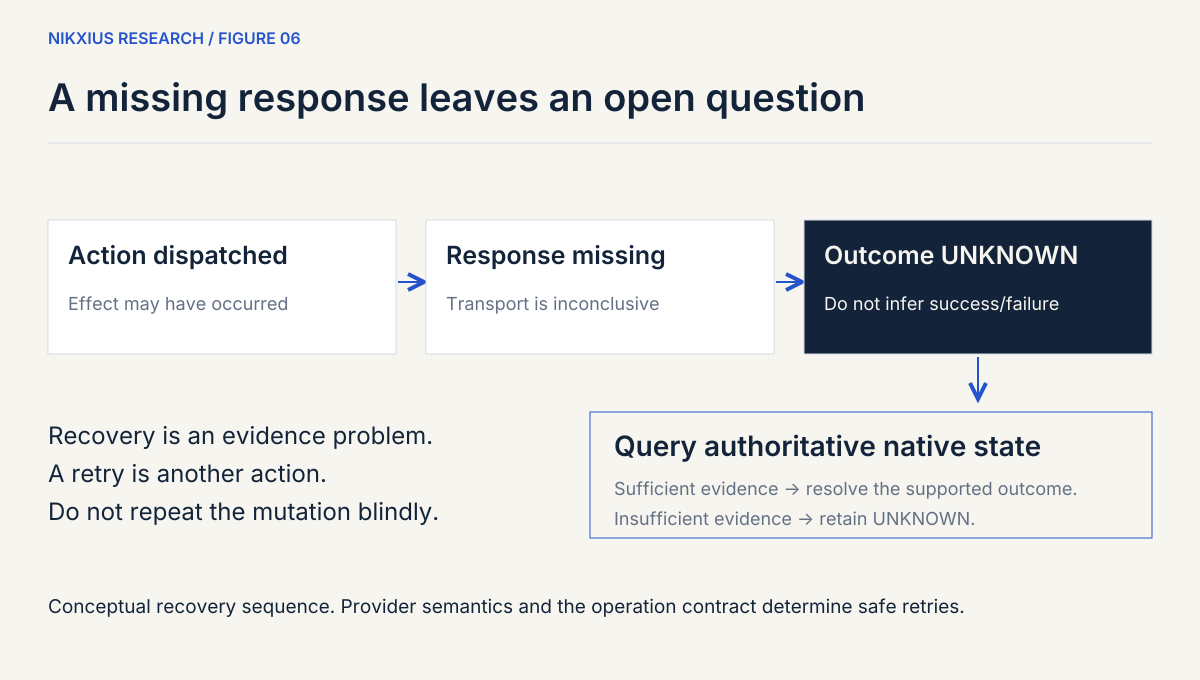
Read the paperAn engineering framework for prompt injection, bounded agent authority and uncertain external outcomes, with explicit limits on what controls establish.
Read the paperPublished by Nikxius Inc. These papers are not peer reviewed. The synthetic example is an inspectable engineering illustration, not a financial-domain benchmark or evidence of customer acceptance.
A visual introduction
A short film on the evidence behind an AI deployment decision.
AI-generated voice narration. The film uses synthetic evidence and conceptual diagrams; it makes no model calls during playback. Read the transcript.
The argument, diagrammed
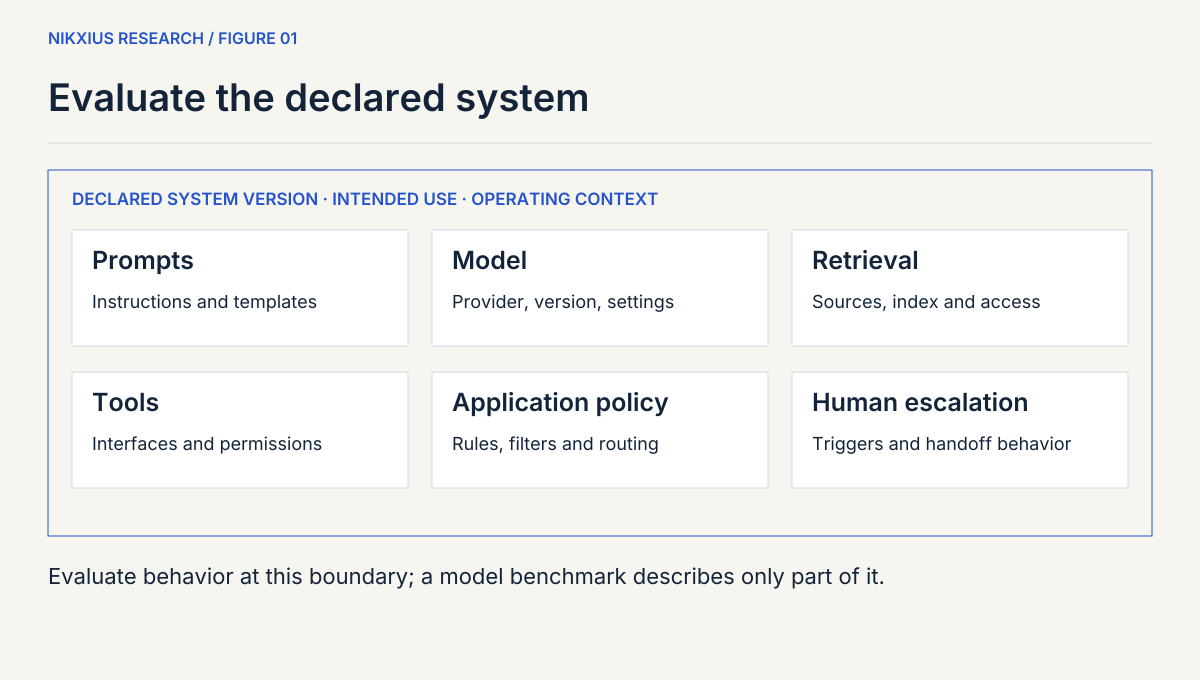
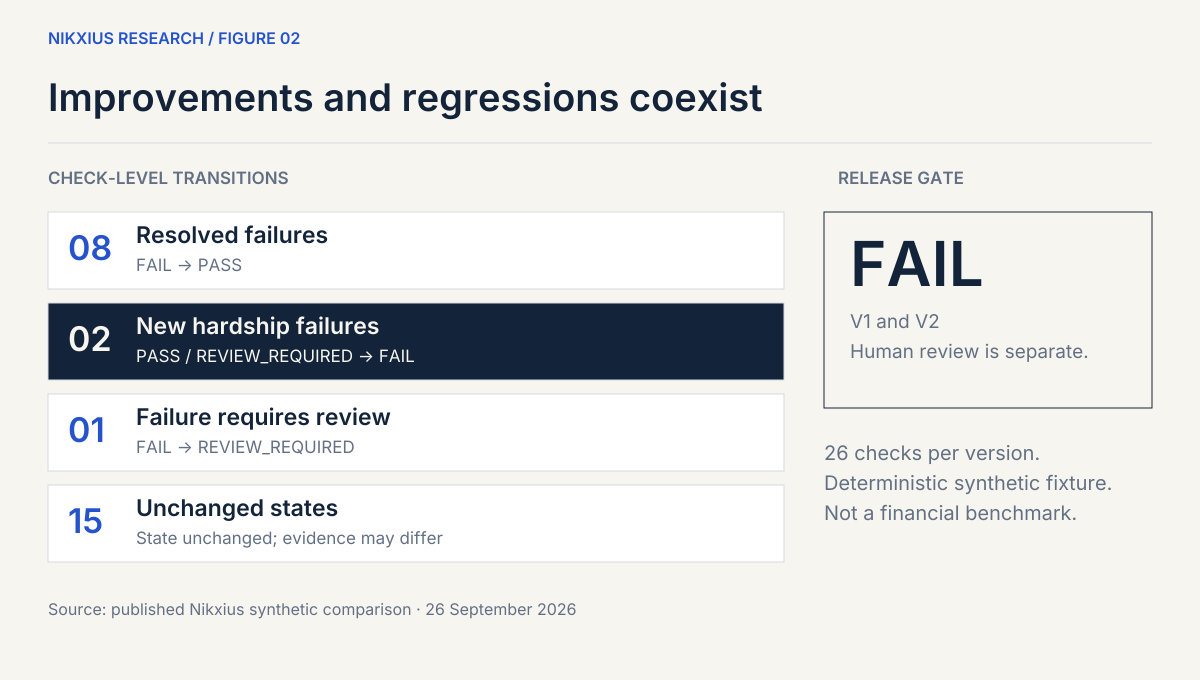
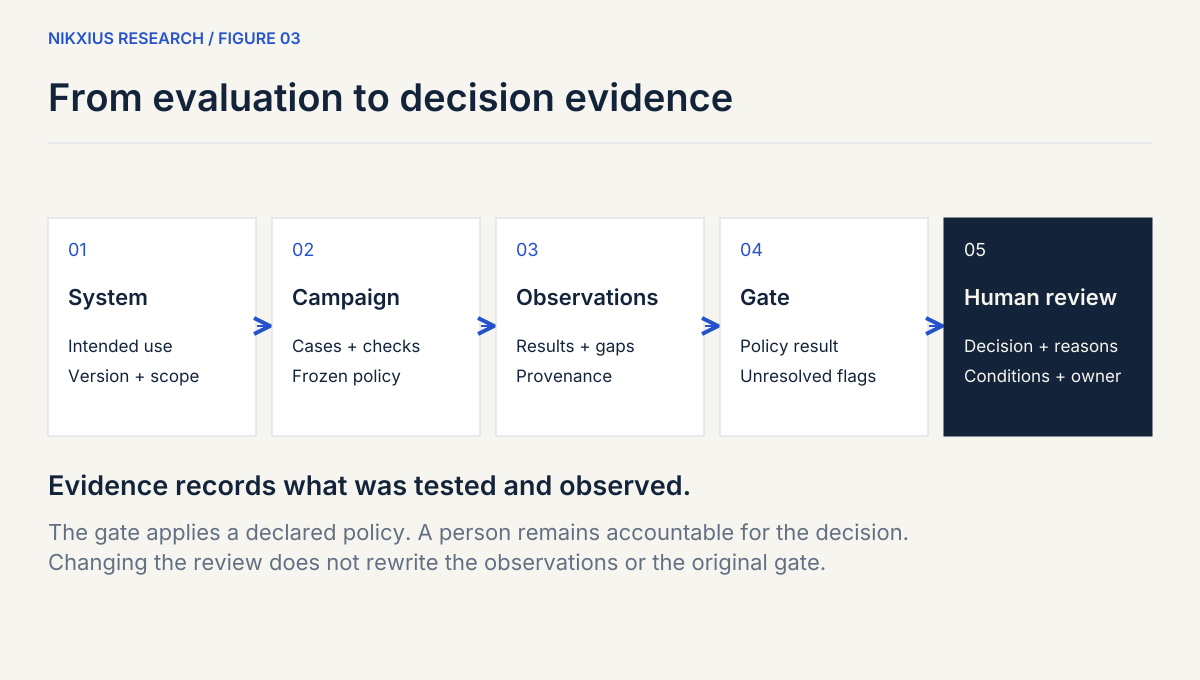
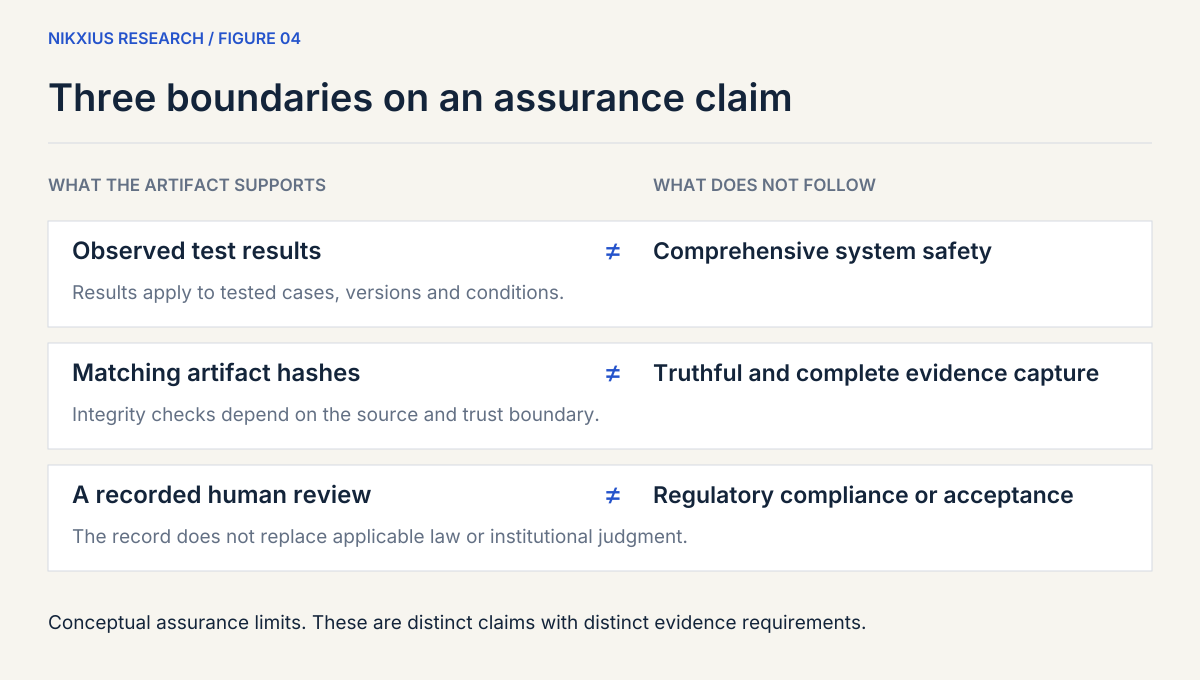
Each figure opens at full size. Read it with the source notes and limitations in the corresponding paper.
The research question
Our current question: does a recurring evidence gap remain after institutions extend the tools and expertise they already have?
Selected source review, not customer validation.
The FCA’s AI Live Testing materials discuss evaluating systems in deployment context, including governance, human oversight and input/output controls. That supports investigating context-specific evidence for review.
It is an exploratory UK programme. Participation does not establish independent purchases of a Nikxius product, universal regulatory requirements or endorsement.
FCA: AI Live Testing and deployment contextEvaluation cases, version comparison and governance workflows already exist. Palantir AIP Evals documents evaluation and comparison. Promptfoo supports evaluations, red teaming and CI. Langfuse’s Trade Republic account describes sustained use of existing tooling.
These published descriptions are not independent trials or complete cost comparisons. They are strong reasons to test whether extending an incumbent workflow already solves the problem.
The local demonstrator can bind system configuration, frozen cases, observations, version comparisons, explicit gates and human review into an exported evidence package.
The public sample contains 26 checks per version, 8 resolved failures and 2 new failures. These are synthetic engineering observations, not financial-domain performance or customer results.
Inspect the captured evidenceRepeatable unmet demand, the actual buying committee, willingness to pay, representative evaluation validity, institutional acceptance, onboarding cost and durable advantage remain open.
The next useful evidence is a reconstruction of a recent review, including the best existing alternative. A well-served organization is an informative result.
Earlier work remains available with its original scope, dates and sources. It does not establish the current Assurance product thesis.